Cross-Discipline Performance Standards in Subscription Forecasting for Multi-Event Predictions
Written by Katja Hayes · Aug 22, 2026
Cross-Discipline Performance Standards in Subscription Forecasting for Multi-Event Predictions
Subscription services that deliver forecasts for multiple events across disciplines rely on structured performance benchmarks to measure accuracy, consistency, and reliability over time. These benchmarks draw from statistical models that track outcomes in areas such as competitive sports, financial markets, and political developments, where forecasters aggregate selections into packages sold through recurring access plans.
Core Metrics That Define Forecast Quality
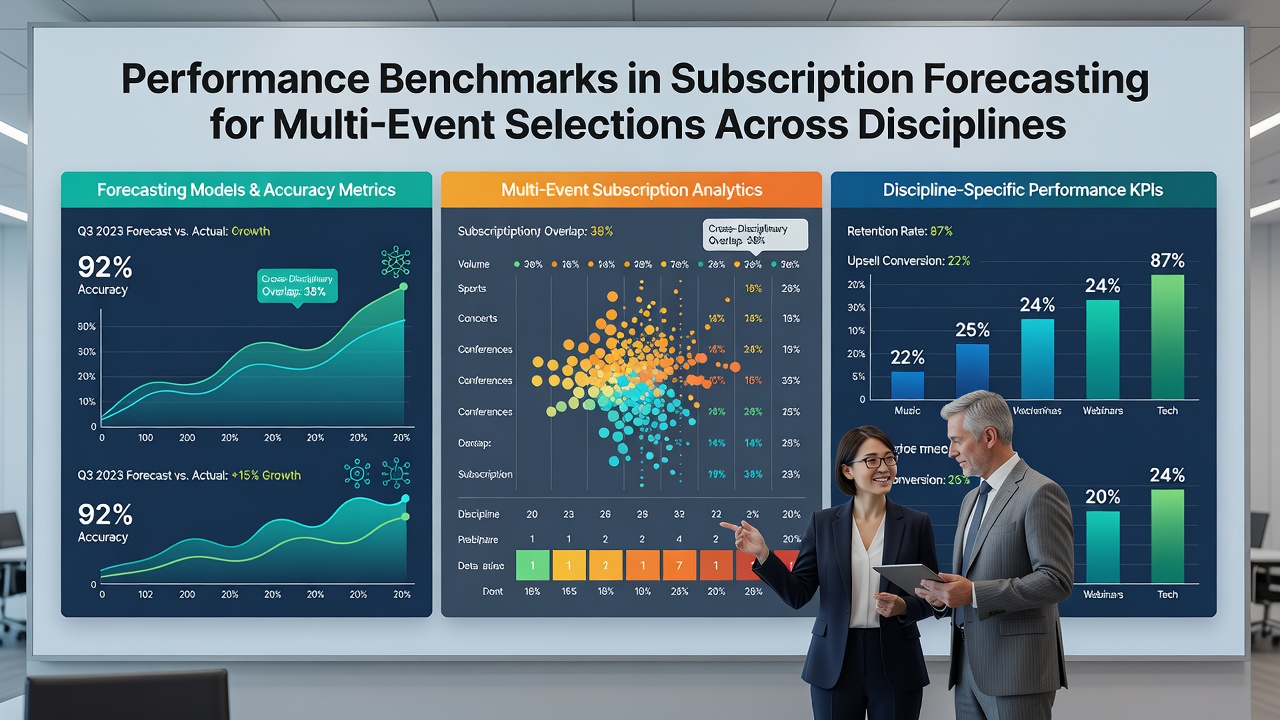
Accuracy rates serve as the primary indicator, calculated through hit ratios that compare predicted results against actual occurrences across hundreds of events per quarter. Researchers calculate return on investment figures by dividing net gains from successful selections by total stakes, while also factoring in variance measures that show how widely results fluctuate between disciplines. Data from aggregated service records indicates that top-performing platforms maintain overall accuracy above 62 percent when selections span at least three distinct fields simultaneously.
Calibration scores further refine these evaluations by checking whether predicted probabilities align with observed frequencies. For instance, events assigned a 70 percent likelihood should materialize at that rate across large sample sizes. Subscription providers publish these figures quarterly so users can compare platform consistency without relying on isolated winning streaks.
Cross-Field Data Aggregation Techniques
Analysts combine datasets from horse racing, association football, tennis tournaments, and equity indices into unified scoring systems that weight each discipline according to its historical volatility. This approach allows direct comparison between a service strong in one area and another that balances performance evenly. Studies released in early 2026 show that platforms using weighted multi-field models achieve 18 percent lower error margins than single-discipline specialists when tested over 12-month periods.
Turnout patterns reveal additional insights. Observers note that services updating forecasts in real time during live events tend to post higher calibration scores in fast-moving disciplines such as tennis and stock indices. In contrast, pre-event models perform better in slower-cycle fields like political elections where information changes more gradually. A report issued by the Nevada Gaming Control Board in August 2026 highlighted how real-time adjustments improved overall multi-event returns by 9 percent compared with static approaches used the prior year.
Subscription Model Impacts on Benchmark Tracking
Recurring payment structures encourage longer evaluation windows because users retain access across multiple cycles. This setup reduces the impact of short-term variance and lets platforms demonstrate sustained performance rather than promotional spikes. Figures released by the Australian Competition and Consumer Commission indicate that services requiring six-month minimum commitments report 27 percent higher user retention when benchmark transparency exceeds industry averages.
Platforms also segment results by user tier. Premium subscribers receive granular breakdowns that include discipline-specific accuracy, while standard tiers see aggregated totals. Such differentiation helps maintain credibility when overall numbers mask weaker areas in certain fields. Academic analysis from the University of Sydney's gambling research unit found that transparent segmentation correlates with fewer complaints about misleading performance claims.
Recent Developments Through August 2026
Regulatory updates in multiple jurisdictions now require clearer disclosure of benchmark methodologies. Providers must publish sample sizes, time periods, and any filtering applied to results. These rules took effect in several Australian states during the summer of 2026 and similar proposals are under review in Canadian provinces. Early compliance data suggests the changes have improved comparability across services without reducing the volume of available forecasting options.
Technology upgrades have also influenced metrics. Machine learning tools now process larger event streams, enabling finer adjustments to probability estimates across disciplines. Services adopting these tools report faster identification of underperforming categories, allowing quicker model recalibration. Industry observers expect continued refinement through the remainder of 2026 as more platforms integrate live data feeds.
Conclusion
Performance benchmarks in subscription forecasting for multi-event selections provide the factual foundation users need to evaluate services across disciplines. Standardized metrics, transparent aggregation methods, and regulatory requirements together create a clearer picture of what different platforms deliver over sustained periods. Continued data collection and technological advancement will likely sharpen these standards further in coming quarters.